01 / OVERVIEW
Context & problem
Contributing to an AWS-based enterprise AI data lake and chatbot initiative that helps users discover and interact with enterprise information through conversational AI.
Reliable enterprise retrieval depends on clean ingestion, synchronized data sources, and useful retrieved context. The work spans data preparation and application integration, not only prompting a model.
02 / SYSTEM ARCHITECTURE
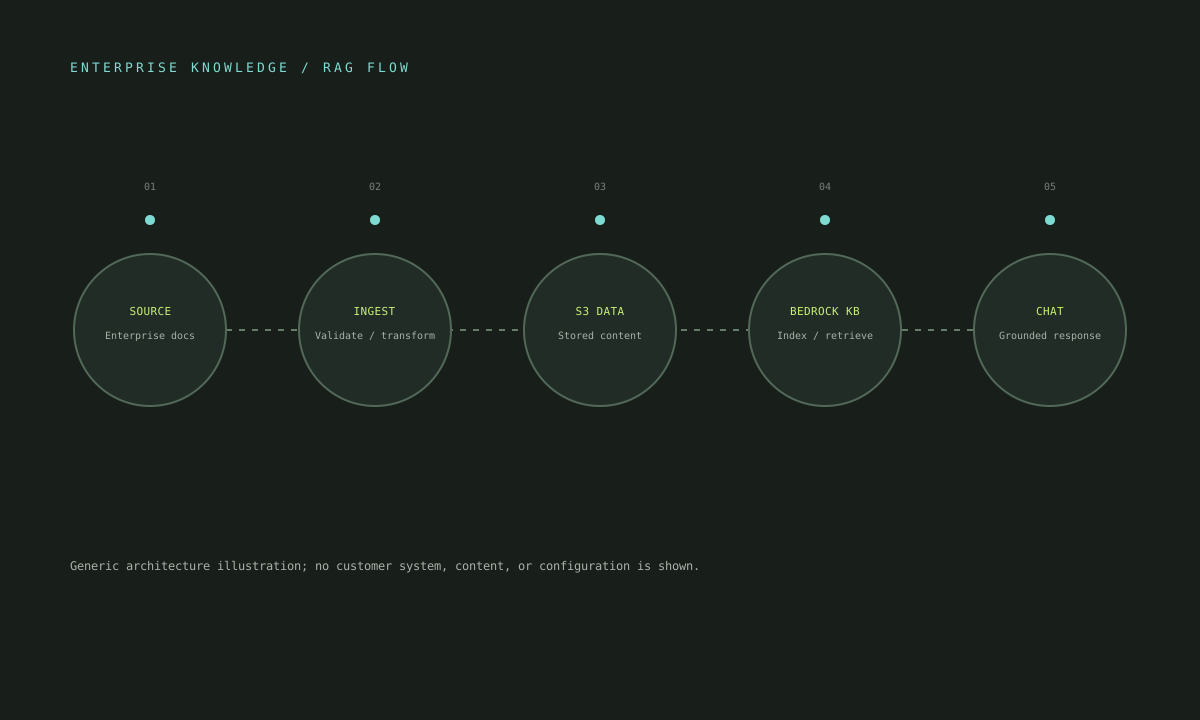
How the pieces connect.
Illustrative architecture with generic labels; it is not a disclosure of customer systems or data.
03 / INDIVIDUAL CONTRIBUTION
What I worked on.
- Built workflows to extract, validate, normalize, and load enterprise content into S3-backed storage.
- Architected and implemented Amazon Bedrock Knowledge Bases and source synchronization workflows.
- Developed Node.js/JavaScript service integrations and endpoints.
- Worked on Terraform infrastructure, CI/CD, retrieval evaluation, architecture discovery, and knowledge transfer.
04 / IMPLEMENTATION
Engineering details.
Reliable enterprise retrieval depends on clean ingestion, synchronized data sources, and useful retrieved context. The work spans data preparation and application integration, not only prompting a model.
- Enterprise content flows through ingestion and transformation before landing in S3.
- Bedrock Knowledge Bases manage embedding, indexing, and retrieval over configured data sources.
- Retrieved context feeds grounded responses in the chatbot application.
- Retrieval tests inspect context relevance and response grounding.
05 / RESULTS & VALIDATION
What the work supports.
- Implemented retrieval workflows that make enterprise documents available to the chatbot.
- No customer-specific data, architecture, or confidential implementation detail is shown.
Validation details are limited to evidence stated in the resume; no unreported datasets, accuracy claims, or benchmark comparisons are added.
MORE WORK
Browse all project case studies GitHub profile