01 / OVERVIEW
Context & problem
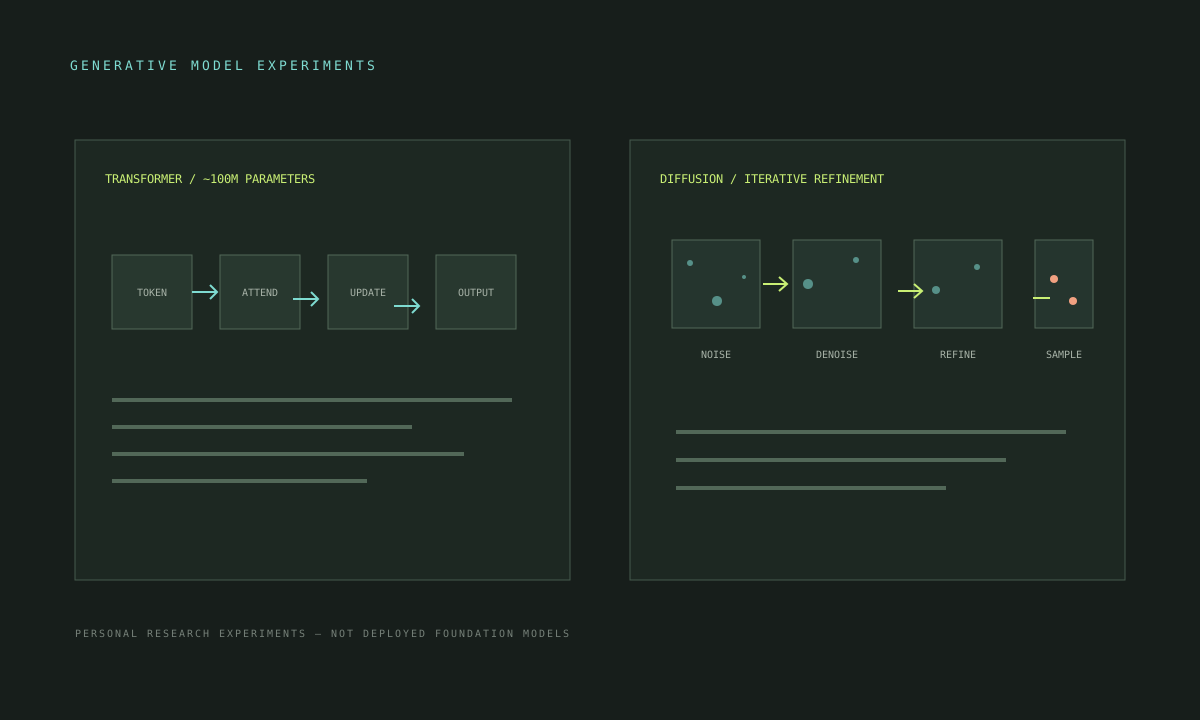
Personal experiments building practical experience with language-model pretraining and reproducing early DALL·E-era diffusion research on ImageNet.
Model training requires coordinating data preparation, architecture, optimization, and evaluation while understanding the compute and iteration costs of each experiment.
02 / SYSTEM ARCHITECTURE
How the pieces connect.
Research and personal experimentation; not a commercially deployed foundation model.
03 / INDIVIDUAL CONTRIBUTION
What I worked on.
- Ran pretraining experiments with language models at approximately 100M parameters.
- Reproduced diffusion-model research workflows on ImageNet.
- Explored transformer architectures and generative-model training.
04 / IMPLEMENTATION
Engineering details.
Model training requires coordinating data preparation, architecture, optimization, and evaluation while understanding the compute and iteration costs of each experiment.
- Experiments covered training and evaluation workflows in PyTorch.
- These were research and personal experiments, not commercially deployed foundation models.
05 / RESULTS & VALIDATION
What the work supports.
- Built practical familiarity with pretraining and diffusion-model reproduction.
- No commercial deployment or benchmark comparison is claimed.
Validation details are limited to evidence stated in the resume; no unreported datasets, accuracy claims, or benchmark comparisons are added.
MORE WORK
Browse all project case studies GitHub profile